Behavior Insight Engine
An AI-native internal dashboard prototype built to enrich unstructured financial transaction strings into formatted, categorized behavioral intelligence. Implements strict client-server boundaries, sliding-window Promise pools, and trace observability telemetry drawers.
Tech Stack
The Problem & Target Constraints
Financial transactions are exported as messy, unstructured strings (e.g. 'AMZN MKTP US*2A4L'). Traditional programmatic regex tools fail to normalize these because string variants are infinite, while LLMs are slow, hit rate limits, and make mathematical calculation errors when asked to aggregate columns.
Real-World Impact: Without reliable normalization, behavioral data analysts cannot extract spending habits or category velocities. Additionally, if the AI fails or returns invalid schemas, typical web dashboards crash.
System Architecture & Flows
Direct client-side visual model mapping of data transactions, lifecycle schemas, and event hooks.
Deep-Dive Engineering Challenges
Below is a structured breakdown of the difficult constraints and tradeoffs resolved during the design phase.
Challenge 01: Managing API Rate Limits during High-Throughput Batches
SYSTEM_STABILITY: ACTIVE// The Problem
Uploading a CSV containing 100+ transactions sequentially takes minutes. However, pushing all 100 rows in one massive concurrent batch triggers immediate API rate limit rejections (429 Too Many Requests).
// Why It Was Difficult
Traditional sequential requests are too slow for UX, but full concurrency crashes the pipeline.
// The Solution
Created a sliding-window Promise pool using a custom queue helper. The queue divides the transaction array into batches of 15, allowing a maximum of 3 concurrent network requests, progressively hydrating the Zustand state as each batch resolves.
// Pragmatic Tradeoffs
Increases client memory footprint during live queue processing, but keeps transaction velocities high while avoiding rate limit blocks.
Challenge 02: AI Schema Hallucination & State Reliability
SYSTEM_STABILITY: ACTIVE// The Problem
LLMs occasionally return JSON responses with missing keys or invalid data types, which causes client components rendering the grids to crash.
// Why It Was Difficult
Writing dozens of manual try-catch logic statements for every JSON key is messy and unmaintainable.
// The Solution
Defined a strict Zod schema validating the structured JSON returned by the Gemini SDK. The Zod parse block sits at the API boundary; if the data is malformed, Zod throws, the catch block flags that specific row as FAILED, and the UI degrades gracefully without crashing the workspace.
// Pragmatic Tradeoffs
Invalid AI responses are discarded instead of repaired, but the entire platform remains stable and responsive.
Challenge 03: Ensuring User Trust in Black-Box AI Processing
SYSTEM_STABILITY: ACTIVE// The Problem
Data analysts refuse to trust AI-generated categorizations if they cannot audit how the decision was made.
// Why It Was Difficult
Logging model outputs to standard developer terminals does not help the actual non-technical analyst checking the UI.
// The Solution
Built a slide-out Observability Telemetry drawer. Clicking any enriched row opens a drawer exposing the exact raw input, model reasoning strings, confidence scores, processing latency, and tracing IDs.
// Pragmatic Tradeoffs
Requires the model to output a 'reasoning' string (which slightly increases token count and latency), but builds profound user trust.
Architecture & Execution Decisions
// Core Pipeline Design
The Behavior Insight Engine acts as a stateless, progressive workspace. A PapaParse helper handles CSV parsing on the client, pushing the raw rows to a Zustand state machine. The Zustand store orchestrates the Promise pool batches to Next.js API Routes. The API route calls the Gemini SDK, passing a strict response schema to force JSON output. The returned data passes through the Zod validation block before mutating the Zustand store and progressively rendering the UI grid.
// Interface Orchestration
The system separates AI synthesis from math: Gemini only normalizes merchant names and categorizes strings. Programmatic JavaScript methods then handle category spend velocities and charts (Recharts), ensuring mathematical accuracy.
// Media & Memory Bounds
To export data, custom CSS print stylesheets are set up. If a user clicks 'Export Report', the dark-mode layout automatically shifts to a high-contrast, ink-saving black-and-white grid template for printing.
Production Screenshots & Gallery
Select and maximize thumbnails below to audit raw workspace interfaces and active dashboards.
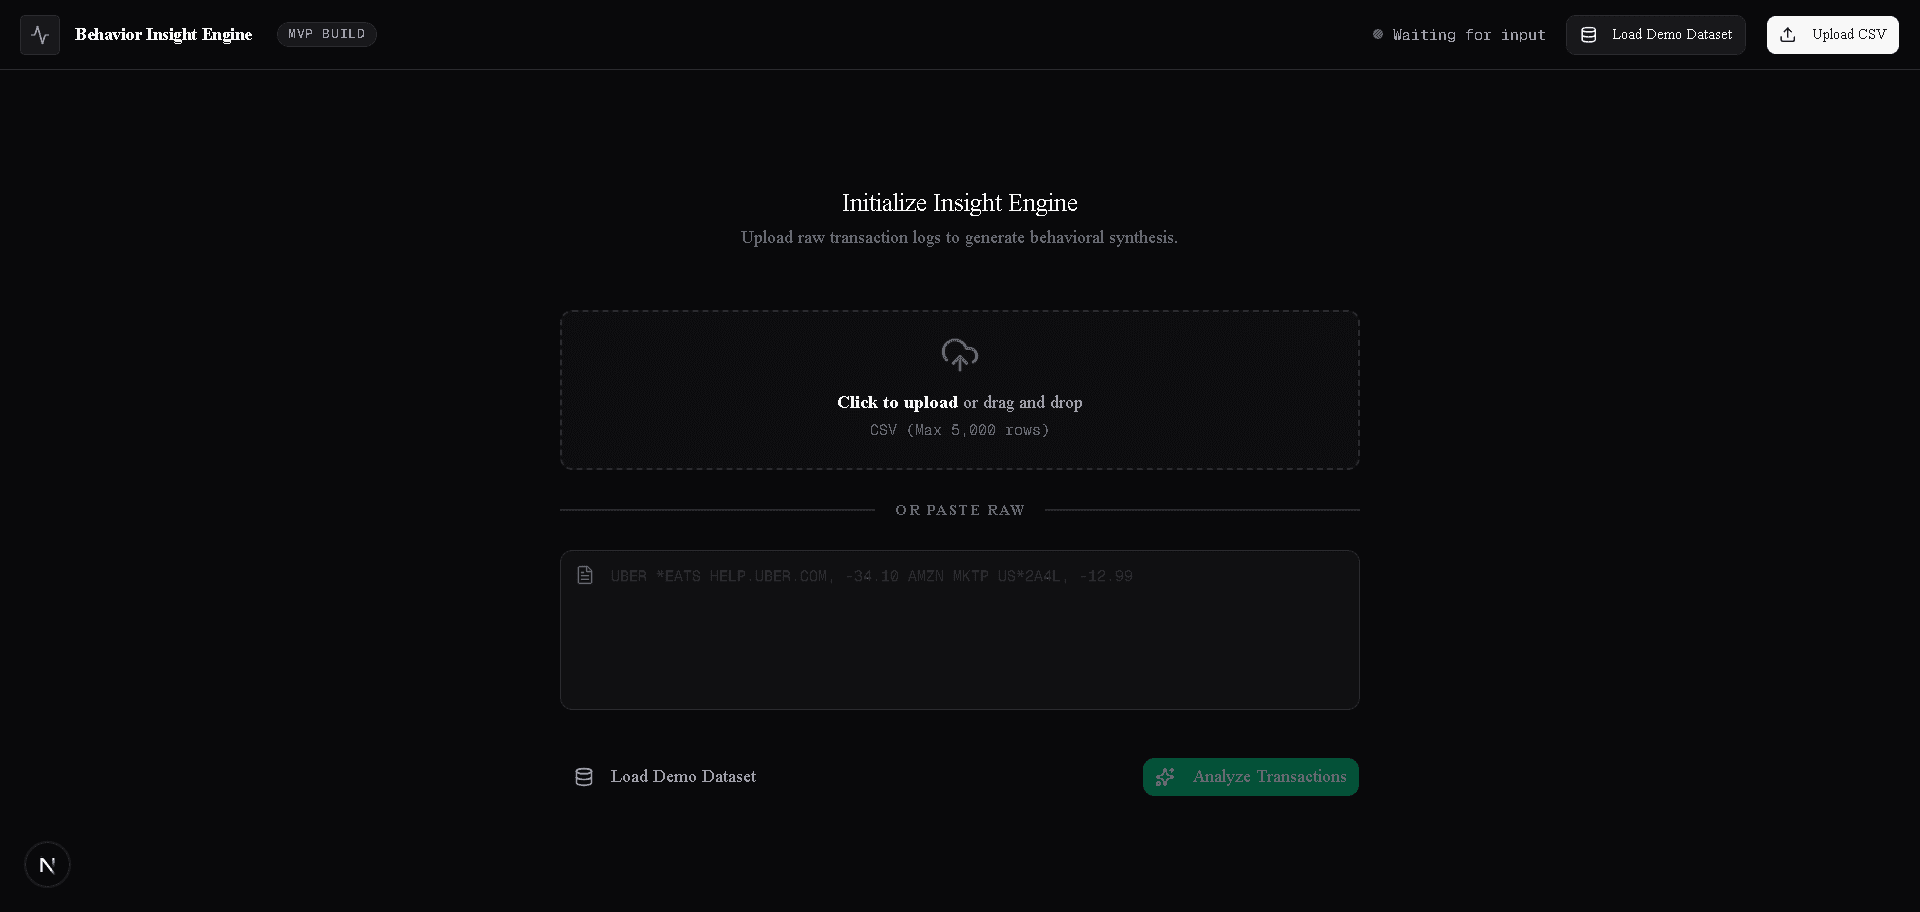
Behavior Insight Ingestion View: Stateless workspace landing page featuring drag-and-drop CSV upload templates.
Detailed Technical Highlights
Observability Telemetry
Row-level logging exposing model inputs, outputs, confidence levels, and latencies.
Concurrency Queue
Sliding-window promise pool processing batches without triggering rate limits.
Defensive Zod Boundaries
Validating AI schemas at the API layer to trap hallucinations before state mutations.
Lessons & Engineering Retrospectives
System Successes
Separating AI classification from arithmetic worked perfectly—charts are 100% accurate, and merchants are clean.
Areas to Optimize
For production scaling, this stateless queue must be migrated to a backend worker queue (like BullMQ/Redis) to persist state during browser disconnects.
Operational Learnings
AI applications must be designed defensively. You must expect the LLM to return garbage, write schemas to catch it, and build tools to audit its decisions.
Interactive Video Walkthrough
Watch a complete structural screen-cast demonstration detailing the pipeline routing, interface mechanics, and active ledger locks.